Semantic Integrity Checks That Catch Injected Instructions Inside RAG Retrieved Chunks
Multiple detection layers catch both explicit and semantic injection attacks in RAG systems.
Selah Beck
Section
14 stories in Prompt Injection.
Multiple detection layers catch both explicit and semantic injection attacks in RAG systems.
Vendors' detection placement and payload coverage determine whether RAG systems stay safe.
Protect AI systems by catching poisoned documents before they enter the knowledge base.
Secure RAG systems by filtering malicious payloads at every pipeline stage.
How LLMs confuse instructions from data in two dangerous ways.
Enterprises can't patch prompt injection, but three-layer defense reduces the damage.
Attackers exploit retrieved documents to inject malicious instructions into LLM systems.
Layered defenses reduce prompt injection risk, but no single pipeline can eliminate it entirely.
Fine-tuned classifiers catch most injections, but evasion techniques defeat them consistently.
Two overlooked attacks can steal a model's secret instructions through different methods.
Buried instructions in emails and documents can hijack AI agents that access private data.
Prompt injection and jailbreaking attack different system layers and require separate defenses.
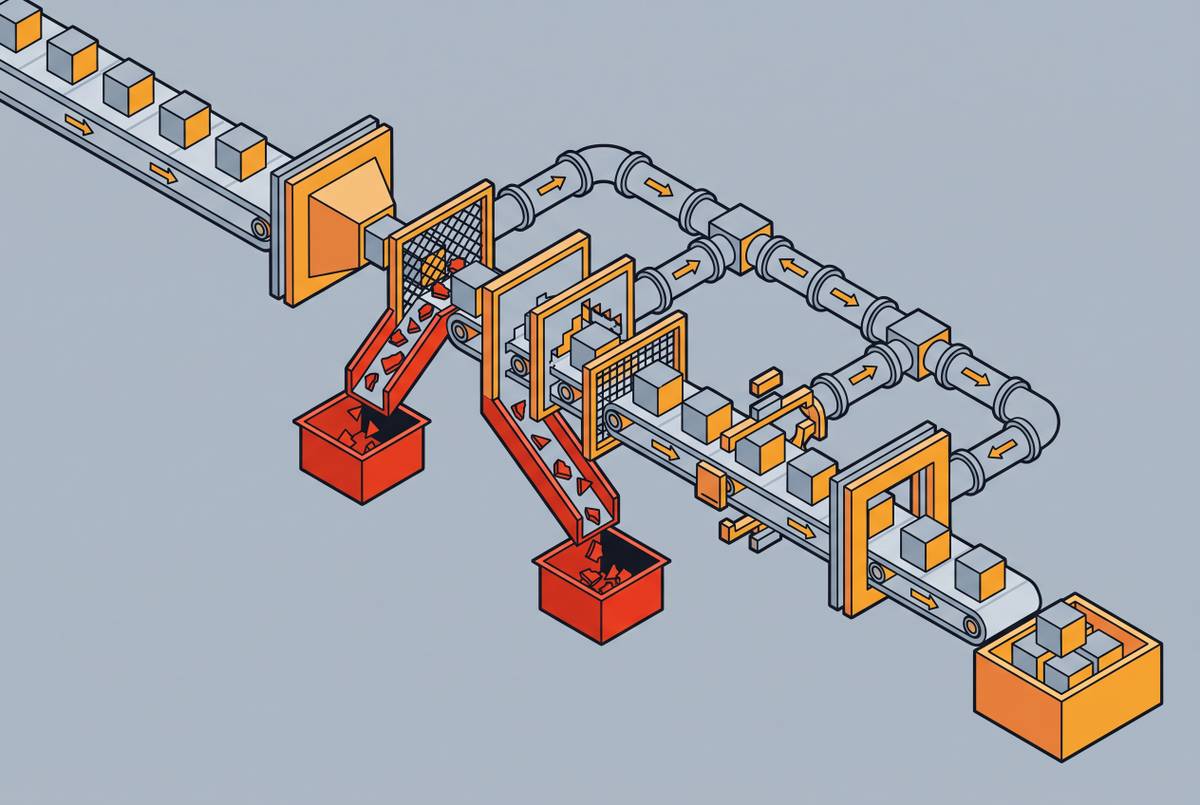
Stacking four detection layers beats relying on any single method to stop prompt injection attacks.