vendors mapping AI security tools to the OWASP LLM Top 10 framework
A shared vocabulary turns risk checklist into tool comparison grid.
Vendors across the AI security market now describe their products in the same ten-category language: prompt injection, sensitive information disclosure, excessive agency, and the rest of the OWASP LLM Top 10. That shared vocabulary has turned a risk checklist into something closer to a coverage map: it's the grid buyers use to compare tools, and the grid vendors use to explain what their product does and doesn't catch.
The OWASP LLM Top 10 as the organizing spine of the AI security vendor market
Security teams needed a way to talk about a problem their existing tools weren't built for. Frameworks like MITRE ATT&CK and standard AppSec checklists assume a system where instructions and data travel through separate channels. The OWASP LLM Top 10 gave buyers named categories for risks that had been hard to even describe out loud. SecureLayer7's AI security practice calls it the first checklist most security teams reach for when scoping AI security work, valuable mainly because it turns complicated AI security ideas into plain, actionable guidance. The list now sits inside a larger OWASP GenAI Security Project, next to an Agentic Top 10 and an MCP Top 10 still in beta, and that's how you know the attack surface has grown past the base model itself. MITRE ATLAS and NIST AI 600-1 both point back to the OWASP list as the application-layer reference under their own more governance-focused or attacker-tactics-focused views.
Turning a risk list into a product coverage map
Vendors didn't just cite OWASP for credibility. They rebuilt how they describe their products around it, because the list gave buyers a common grid to compare tools on, and its ties to regulation made that grid feel like more than marketing. Three things pushed vendors toward this structure. A shared vocabulary cuts down friction in sales conversations: when a vendor publishes which categories its controls address, a buyer skips the step of defining terms and moves straight to spotting gaps. The 2026 edition also dropped its old per-entry framework links and put in one appendix that maps every risk to nine external frameworks, each with a pinned version, so a vendor's OWASP alignment now carries those downstream regulatory requirements along with it. And the 2026 ranking itself now rests on incident data as well as practitioner opinion: a Bayesian measurement-error model was run against thousands of real-world incidents to build the incident-based part of the score, which gives a vendor a concrete answer when a buyer asks why one category outranks another.
AWS shows what this looks like at full scale. Amazon published prescriptive guidance mapping its own controls to all ten OWASP LLM categories, including Amazon Bedrock Guardrails against LLM01 Prompt Injection for filtering malicious input patterns, and against LLM02 Sensitive Information Disclosure. A major cloud provider treating the OWASP list as a documentation standard for its own products, not just a reference it nods to, tells buyers something about how far this adoption has gone. When security teams have already mapped their internal risk registers to OWASP categories, they tend to favor vendors whose materials are organized the same way, and that preference pushes still more vendors toward the same format.
The 2025 and 2026 editions, and the version gap buyers face
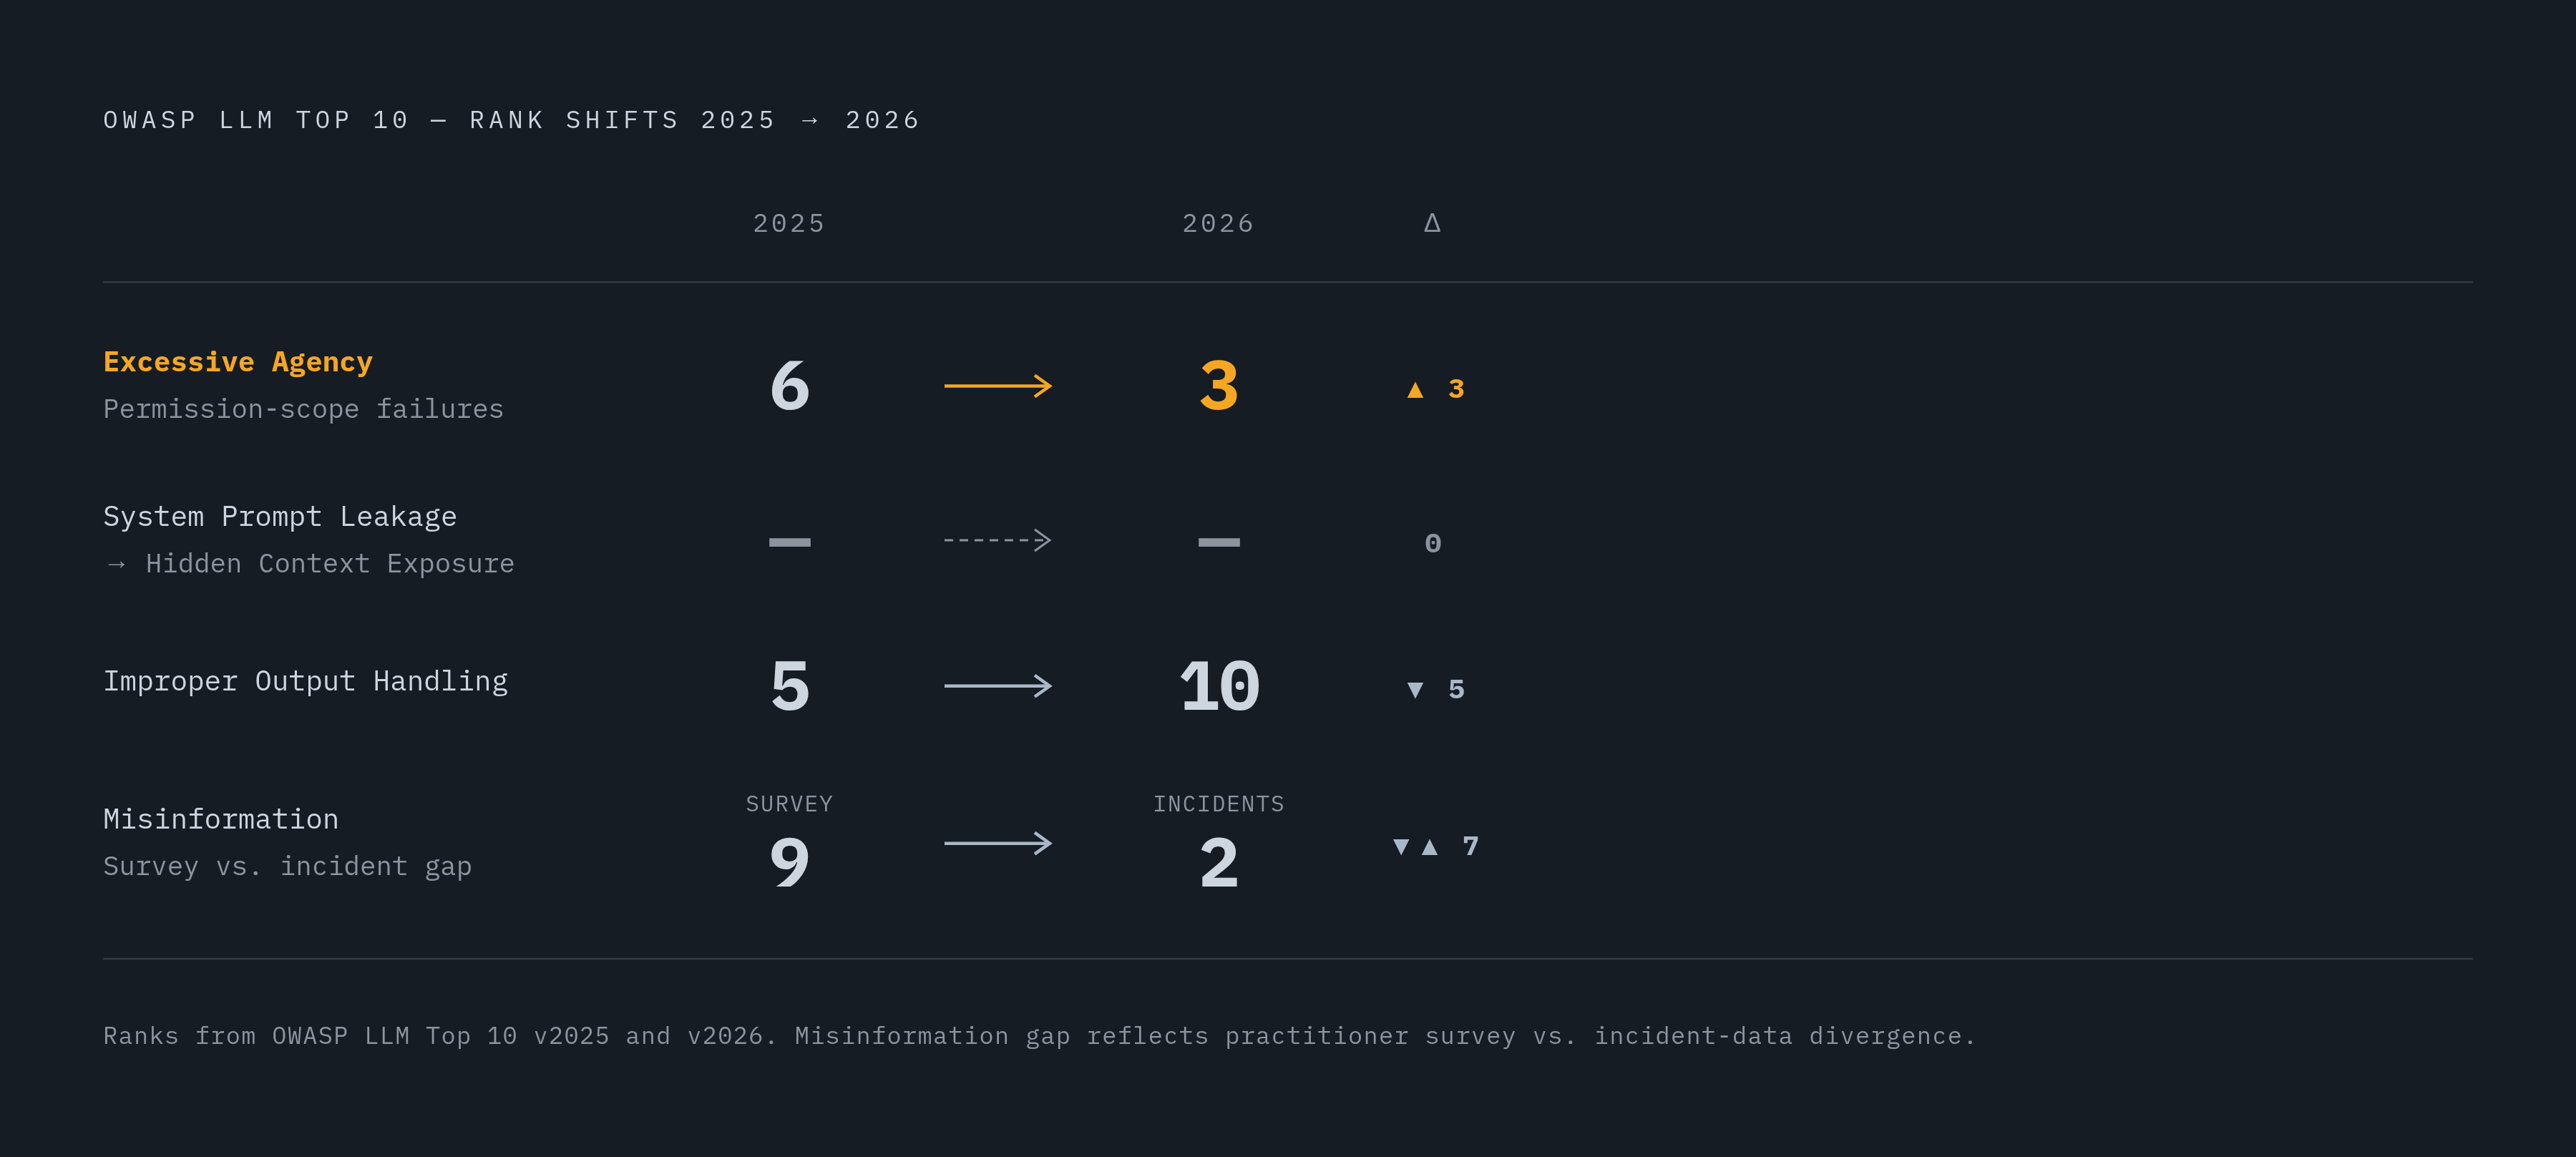
LLM04: Data and Model Poisoning expanded from the narrower "Training Data Poisoning" to cover model weights. LLM05: Improper Output Handling covered the downstream trust failures that happen when model output reaches browsers, databases, or APIs. LLM06: Excessive Agency was rewritten for real agent products, about permission scope rather than just which functions a model could call. LLM07: System Prompt Leakage entered as new in 2025, replacing Insecure Plugin Design rather than splitting off from prompt injection. LLM08: Vector and Embedding Weaknesses also entered new in 2025, covering attacks against RAG pipelines. LLM09: Misinformation replaced Overreliance and expanded to include hallucinations that downstream systems act on. LLM10: Unbounded Consumption replaced Model Denial of Service with a wider scope covering resource drain and model theft. The 2025 edition, the current mapping target for most tooling and CTF infrastructure as of early 2026, established the following ranking. Most vendor coverage matrices still reference the 2025 edition, but the 2026 edition is now active, and its ranking changes are significant enough to expose gaps in any tooling aligned to the earlier version.
The 2026 edition, published 3 August 2026, made four changes most vendors have not caught up with yet. Excessive Agency jumped from sixth to third, backed directly by incident data, which signals that permission scope is now a top-three enterprise risk. System Prompt Leakage was renamed Hidden Context Exposure. Improper Output Handling fell from fifth all the way to tenth. The ranking method itself changed too: incident data pulled from public vulnerability databases and an AI-harm database now makes up a quarter of the final ranking, with community voting carrying the rest, so the order rests on measured incidents rather than expert opinion alone. You can check a product against an OWASP coverage matrix today, but you may still be reading a document written against a version the framework has already replaced.
How vendor types divide the ten categories
No vendor covers all ten categories alone without pulling in a partner somewhere, and looking at where different vendor types cluster shows which risks are well-funded and which ones nobody's really built for yet. Runtime guardrail specialists sit closest to the prompt layer. Lakera Guard, now part of Check Point after an October 2025 acquisition, is built for LLM01 and LLM02, and it filters input and output for chat-style applications. Lakera's own documentation says runtime protections can't catch supply chain vulnerabilities (LLM03), which model behavior evaluation addresses only partly, so the vendor names its own gap in writing rather than papering over it.
Cloud-native CNAPP platforms take a different angle, built around posture rather than runtime filtering. Wiz's AI Application Protection Platform discovers AI services across AWS Bedrock, Azure AI, and Vertex AI, checks their configurations, flags exposed training data, and tracks model artifact security and inference endpoint exposure, work that lines up more with LLM03, LLM04, and LLM06 than with LLM01. Specialized application security vendors tend to cover a defined slice and say so: Imperva AI Application Security, now under Thales, addresses five of the ten categories out of the box, a partial-coverage claim stated clearly enough that buyers can see the gap instead of guessing at it. Thales announced its AI Security Fabric in December 2025, adding data leakage prevention, an MCP security gateway, and runtime access control for agentic AI interactions to its 2026 roadmap.
Supply chain risk (LLM03) and data poisoning (LLM04) stay thin across nearly every vendor type. Most enterprises build on third-party models and libraries without a clear AI Bill of Materials, so if a base model is compromised, every application on top of it inherits that risk, and no one may even know it. Standard AppSec tooling wasn't built to catch poisoned RAG chunks or a quietly removed token cap on an inference endpoint, so a scan can come back clean while the actual problem sits untouched. Continuous monitoring platforms that cover a vendor's whole AI ecosystem, rather than a single internal deployment, are built to close that structural gap: PromptArmor, which focuses specifically on third-party AI vendor risk for enterprise security and TPRM teams, is one example of the third-party AI asset an enterprise didn't build and can't instrument directly.
OWASP LLM Top 10 coverage claims that mislead buyers
A vendor can claim a category honestly and still address it shallowly, because the OWASP list defines what the risk is without specifying how deep a control has to go to actually stop it. SecureLayer7's own AI security team treats the framework as a scope-setting tool, not a control framework: it is used to figure out which categories apply to a given architecture, then a payload library gets run against the exact configuration in question, with follow-up attacks built by hand wherever something half-works.
The misinformation category (LLM09) makes the tension in the framework's own data visible. Practitioners voted it near the bottom of the 2026 rankings, while the incident record placed it near the top, the widest gap anywhere on the list. Community intuition and observed harm are pulling in opposite directions there, and a vendor that builds its roadmap around community sentiment will likely under-invest in the exact category the incident data says matters most. Prompt injection (LLM01) shows the mirror image of the same problem: it held first place in the 2026 ranking despite a thin incident record, which OWASP attributes to a defense effect, where heavy investment in the category keeps successful attacks from reaching public databases. That dominance in vendor marketing may say more about where money is flowing than about where harm is actually occurring.
Evidence from the field shows prompt injection is already more sophisticated than most coverage matrices account for. Forcepoint X-Labs catalogued ten indirect prompt injection payloads in April 2026: some hide text through markup that a human reader can't see but the model still parses, and some use white-on-white PDF layers that survive a normal visual check. Standard input-filtering controls may not catch either technique. Buyers have no standard way to check how deep a vendor's coverage actually goes: a vendor can legitimately claim LLM01 coverage by filtering known jailbreak strings while leaving indirect injection through document ingestion completely open.
The rise of agentic architectures outpacing the ten-category map
Agentic AI brought a set of risks the ten-entry LLM list was never built to cover: goal hijacking, tool misuse, cascading failures across multiple agents, agent identity abuse. The vendor market hasn't fully caught up to any of it yet. The OWASP GenAI Security Project responded with the Agentic Top 10, covering what happens once a model gets tools, memory, and the authority to act on its own: agent goal hijack, tool misuse, identity and privilege abuse, agentic supply chain vulnerabilities, unexpected code execution, memory and context poisoning, insecure inter-agent communication, cascading failures, human-agent trust exploitation, and rogue agents.
Excessive Agency's jump from sixth to third in the 2026 LLM Top 10, backed by real incident data, is the clearest sign that the line between the LLM list and the Agentic list is already blurring in practice. Permission scope failures appear in systems already running in production, not only in theoretical agent designs. GoDaddy has already put OWASP's Agent Name Service proposal into production, a named enterprise treating the Agentic framework as something you can run today, not a draft to watch. Microsoft's documentation on agentic failure modes references OWASP's Threat and Mitigations document, and NVIDIA's Safety and Security Framework for Real-World Agentic Systems leans heavily on OWASP's Agentic Threat Modelling Guide, two major platform vendors signaling that these sibling frameworks, not the original LLM list alone, are what their agentic products are actually built against. The MCP Top 10 adds a third layer still: the narrower protocol connecting an agent to external systems, which any deployment running on the Model Context Protocol needs its own place on the evaluation grid.
A coverage matrix built only on the LLM Top 10 doesn't reach the agentic layer. If a vendor's OWASP alignment document was written against a 2025, LLM-only scope, it may be blind to the fastest-growing part of the attack surface, and neither side of the sale may even know it. That's the practical reason a coverage matrix alone, however current, can't be the end of a buyer's evaluation. The ten categories remain the floor for evaluating an AI security tool. They've stopped being the ceiling.
Sources
- OWASP GenAI LLM Top 10 2026 - OWASP Gen AI Security Project
- owasp.org
- OWASP LLM Top 10 (2025): Every Risk Explained
- OWASP Top 10 for Agentic Applications - The Benchmark for Agentic Security in the Age of Autonomous AI - OWASP Gen AI Security Project
- genai.owasp.org
- OWASP’s 2026 LLM Top 10: Incident Data Meets Judgment
- OWASP LLM Top 10 2026: What Changed and Why